Nov 14, 2026
- [Introducing Parallel Image Search](https://parallel.ai/blog/parallel-images-api)
Tags:Product
Author: By Parallel Web SystemsNovember 17, 2026


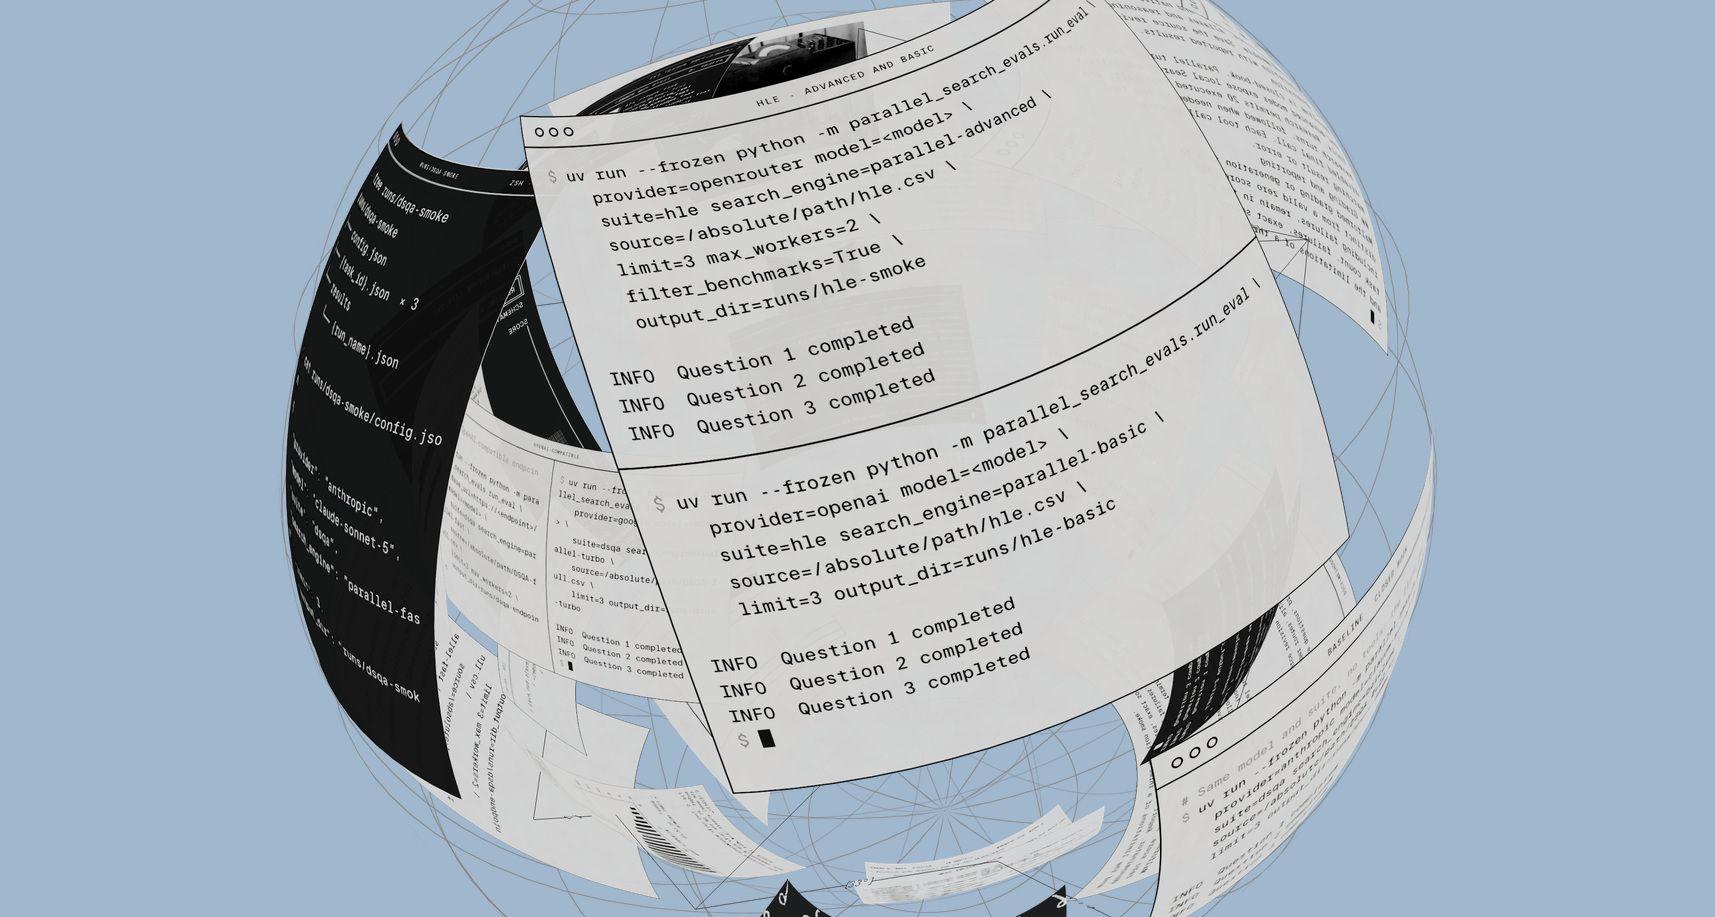
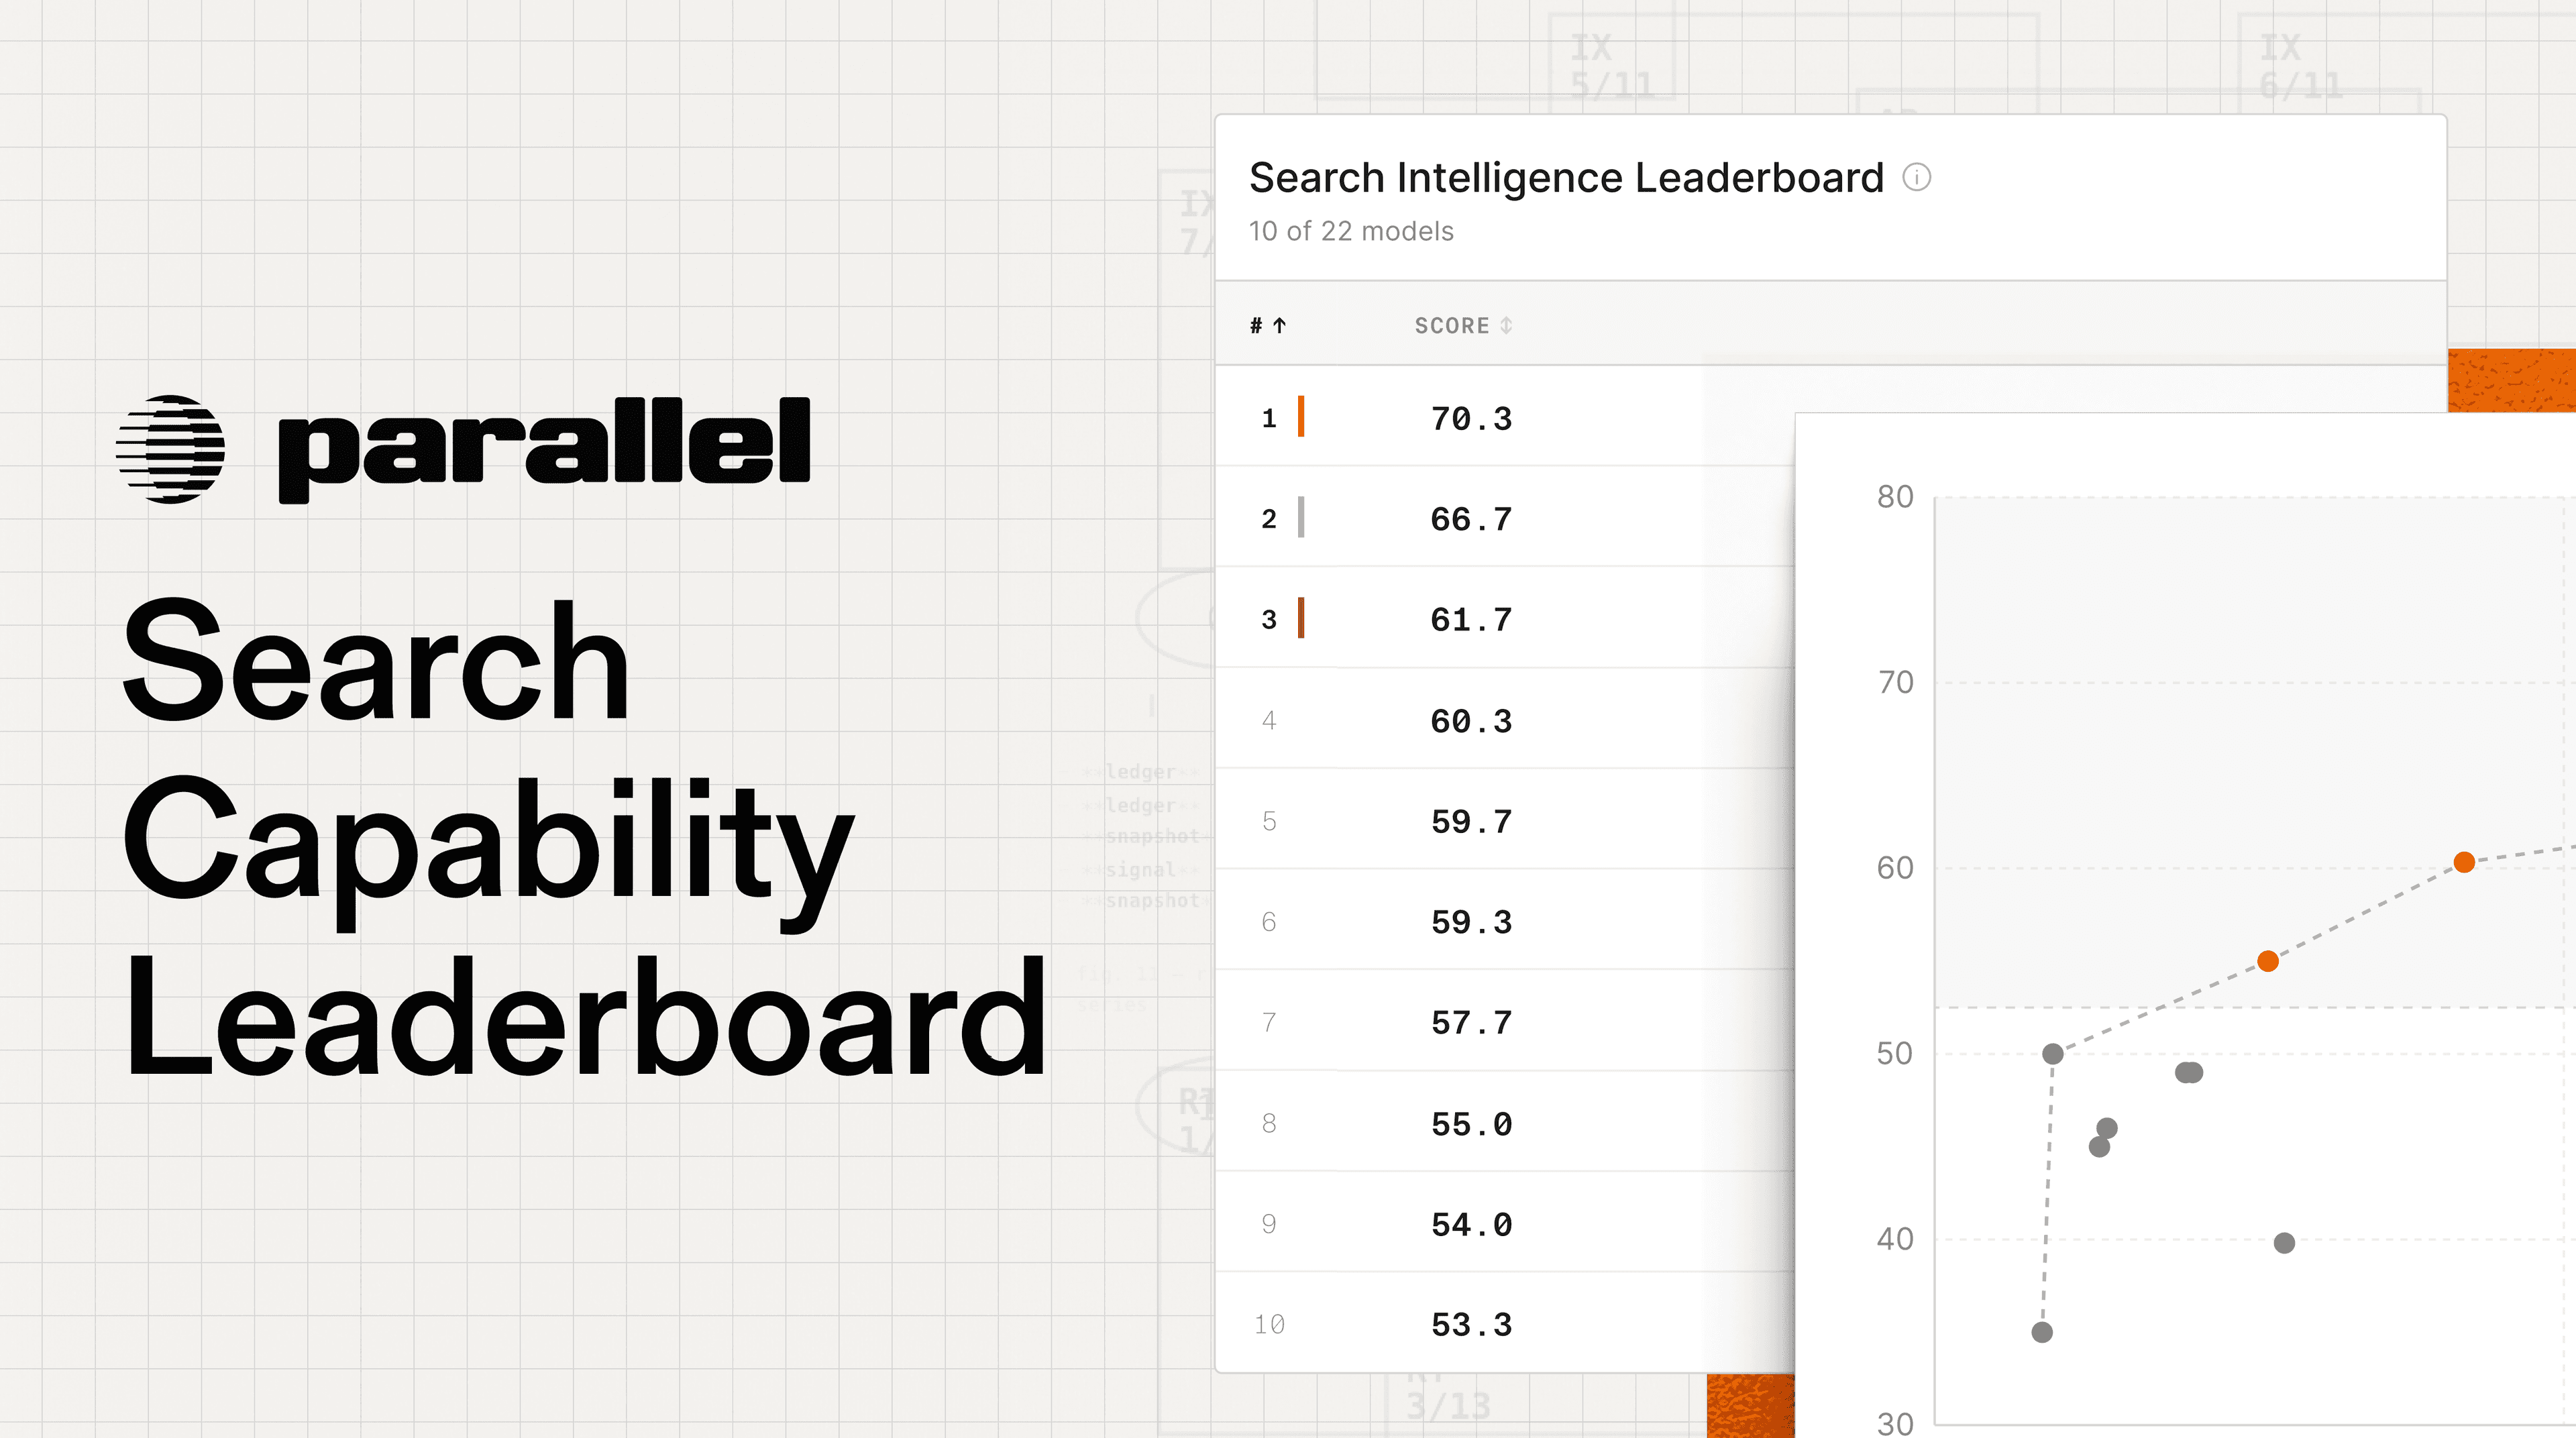
Today we're open-sourcing parallel-search-evals[parallel-search-evals], the eval harness we use at Parallel to measure the performance of Parallel Search, assess new models we deploy internally, and power our Search Capability Leaderboard[Search Capability Leaderboard].
The eval harness is designed to test Parallel Search with any large language model accessible through OpenRouter, OpenAI, Anthropic, Google, or any OpenAI-compatible endpoint.
Evals tend to have a transparency problem. Every few weeks, AI providers publish new charts where their bars are the tallest and the competitors' are shorter. Readers are privy only to the benchmark results, not the model configuration, tools and setup, errors, or discarded failures. Without the ability to reproduce the results themselves, readers have no choice but to blindly trust the publisher.
We believe the most useful evaluations come from testing on data that closely resembles a team’s real workload. By releasing our eval infrastructure, we want to allow teams to first understand how we test Parallel and reproduce our results, then use the harness to repeat those experiments with their own datasets.
We've written a guide on how to evaluate web search for AI[how to evaluate web search for AI], which covers the same principles and can be used alongside this eval harness to conduct an effective evaluation of various LLMs and web search combinations.
Each run evaluates one model on one benchmark in one mode: `turbo`, `fast`, `basic`, `advanced`, or `baseline` (closed-book, no tools). Comparing the `baseline` run with a search run gives you the lift from search.
123git clone https://github.com/parallel-web/parallel-search-evals.git
cd parallel-search-evals
uv sync --frozen``` git clone https://github.com/parallel-web/parallel-search-evals.gitcd parallel-search-evalsuv sync --frozen``` 1234# Three-question smoke test
uv run --frozen parallel-search-evals run \
--provider anthropic --model claude-sonnet-5 \
--benchmark dsqa --mode fast --limit 3 --output runs/dsqa-smoke``` # Three-question smoke testuv run --frozen parallel-search-evals run \ --provider anthropic --model claude-sonnet-5 \ --benchmark dsqa --mode fast --limit 3 --output runs/dsqa-smoke``` The harness can also be modified to compare Parallel against other providers.
Public benchmarks are a starting point. The decision you actually care about lives in your own traffic. The harness keeps the question set separate from the agent loop and the grader, so you can add a suite with your own questions, reference answers, and grading rules while the search setup, budgets, and reporting stay exactly as they are on the leaderboard.
The repo includes an agent skill (`.agents/skills/run-search-evals`) that walks a coding agent through resolving the model, mode, and question count, checking credentials, running, resuming, and summarizing. Point Claude Code or Codex at the checkout and ask it to run the eval.
Search evals need things existing frameworks don't handle well: multi-turn tool calling that behaves the same across providers' native protocols, per-call cost accounting, and recovery when a provider stream dies halfway through a long research trace.
**OpenRouter**[**OpenRouter**] drastically simplifies the harness by offering one integration for hundreds of models. Native OpenAI, Anthropic, and Google adapters keep each provider's own tool-calling and reasoning protocols, including Anthropic's prompt caching and Gemini's continuation tokens.
**Parallel**[**Parallel**] provides two tools: **Search API**[**Search API**] takes a natural-language objective plus short keyword queries, and returns up to 10 results with dense excerpts. **Extract API**[**Extract API**] pulls evidence from up to 20 specific URLs. This reflects best practices we recommend to most customers.
The model gets a 20 tool call **budget** per question. We evaluate this in a deep research mode, giving access to 2 tools; the model is told to forget its internal knowledge and only use these 2 tools, and once it runs out of budget, we ask it to return knowledge based on what it has found during its research.
An OpenAI GPT-6 Sol judge **grades** each answer against the reference with the benchmark's official prompt: F1 for DeepSearchQA (partial credit for incomplete answer sets) and strict correctness for HLE.
If you find a bug, or a choice you think is wrong, open an issue[open an issue].
**Fork the harness on GitHub →**[**Fork the harness on GitHub →**]