Nov 17, 2026
- [Open-sourcing the Parallel Search Eval Harness](https://parallel.ai/blog/parallel-search-eval-harness)
Authors: By James Liounis, Vlad Shulman and Lukas Levert
November 18, 2026

Today we’re launching **Parallel for Healthcare**, an upgrade to our search index and ranking for healthcare and life sciences agents. Agents can find and cite evidence from primary sources including FDA drug labels, ClinicalTrials.gov records, CMS registries and recent research papers indexed in PubMed. The upgrade is available across all Parallel APIs with no new plan or subscription required.
Drug discovery and provider research both depend on evidence scattered across many different public sources. In drug discovery, agents can use Parallel to find compounds that act on a target and check how far each has progressed in clinical trials. For provider research, agents can enrich a list from the NPI Registry with each provider’s research interests and publications relevant to a drug in development. Teams can now verify each finding against the original paper or record without maintaining their own crawling pipelines.
Key takeaways:
We tested six healthcare benchmarks with the same agent, questions and grader, changing only the search provider. The answer model is Claude Opus 5.5 (high effort), and each engine ran three times. The cost metric includes answer-model tokens and search fees at list price. Before scoring, we audited every public answer key and fixed stale or wrong golds for all engines alike. You can find more details on the methodology below each chart.
Correct answers per $
COST (CPM)
ACCURACY (%)
CPM: USD per 1,000 questions, end to end (answer-model tokens plus search and fetch calls at list price).
**Dataset**
PWS-Health is Parallel's private healthcare benchmark: 133 held-out questions with verified answers. 83 are adapted from questions healthcare teams ask Parallel across 10 workflows, and 50 are drawn from recent open-access randomized trials and meta-analyses in PubMed Central. The questions and answers are not published anywhere online.
**Evaluation methodology**
Every search API runs in the same agent loop with the same questions and the same LLM judge, so the search layer is the only variable. Every arm answers with Claude Opus 5.5 (high effort). Claude native search is Claude Opus 5.5's built-in web search. Scores are the mean of three runs.
Cost is end-to-end per answer at list price: the answer model's tokens plus every search and fetch the agent makes, shown per 1,000 questions.
**Testing dates**
Evals were run in November 2026.
**Dataset**
PWS-Health is Parallel's private healthcare benchmark: 133 held-out questions with verified answers. 83 are adapted from questions healthcare teams ask Parallel across 10 workflows, and 50 are drawn from recent open-access randomized trials and meta-analyses in PubMed Central. The questions and answers are not published anywhere online.
**Evaluation methodology**
Every search API runs in the same agent loop with the same questions and the same LLM judge, so the search layer is the only variable. Every arm answers with Claude Opus 5.5 (high effort). Claude native search is Claude Opus 5.5's built-in web search. Scores are the mean of three runs.
Cost is end-to-end per answer at list price: the answer model's tokens plus every search and fetch the agent makes, shown per 1,000 questions.
**Testing dates**
Evals were run in November 2026.
| Series   | Model                | Cost (CPM) | Accuracy (%) |
| -------- | -------------------- | ---------- | ------------ |
| Parallel | Parallel Fast        | 104        | 85.2         |
| Parallel | Parallel Advanced    | 85.3       | 83.7         |
| Others   | Exa                  | 124.6      | 82.5         |
| Others   | Perplexity           | 116.2      | 80.5         |
| Others   | Tavily               | 154.3      | 77.2         |
| Others   | Claude native search | 646        | 66.9         |
CPM: USD per 1,000 questions, end to end (answer-model tokens plus search and fetch calls at list price).
**Dataset**
PWS-Health is Parallel's private healthcare benchmark: 133 held-out questions with verified answers. 83 are adapted from questions healthcare teams ask Parallel across 10 workflows, and 50 are drawn from recent open-access randomized trials and meta-analyses in PubMed Central. The questions and answers are not published anywhere online.
**Evaluation methodology**
Every search API runs in the same agent loop with the same questions and the same LLM judge, so the search layer is the only variable. Every arm answers with Claude Opus 5.5 (high effort). Claude native search is Claude Opus 5.5's built-in web search. Scores are the mean of three runs.
Cost is end-to-end per answer at list price: the answer model's tokens plus every search and fetch the agent makes, shown per 1,000 questions.
**Testing dates**
Evals were run in November 2026.
| Series   | Model                | Cost (CPM) | Accuracy (%) |
| -------- | -------------------- | ---------- | ------------ |
| Parallel | Parallel Fast        | 58.8       | 86.7         |
| Parallel | Parallel Advanced    | 48.8       | 86.7         |
| Others   | Exa                  | 126.3      | 81           |
| Others   | Tavily               | 117.7      | 79.2         |
| Others   | Perplexity           | 73.7       | 79           |
| Others   | Claude native search | 352.3      | 78.2         |
CPM: USD per 1,000 questions, end to end (answer-model tokens plus search and fetch calls at list price).
**Dataset**
LitQA3 is part of FutureHouse's LAB-Bench 2. Each of its 168 questions asks for a specific detail from a recent biomedical paper, such as an effect size in a results table or a step in a methods section, so the engine has to find the right paper and pinpoint the answer.
**Evaluation methodology**
Every search API runs in the same agent loop with the same questions and the same grader, so the search layer is the only variable. Every arm answers with Claude Opus 5.5 (high effort). Claude native search is Claude Opus 5.5's built-in web search. The benchmark's own grader fails on some biology answers, so we re-graded those with the benchmark's prompt for every arm. Answers that reached a published answer key count as wrong. Scores are the mean of three runs.
Cost is end-to-end per answer at list price: the answer model's tokens plus every search and fetch the agent makes, shown per 1,000 questions.
**Testing dates**
Evals were run in November 2026.
| Series   | Model                | Cost (CPM) | Accuracy (%) |
| -------- | -------------------- | ---------- | ------------ |
| Parallel | Parallel Fast        | 57.7       | 96.3         |
| Parallel | Parallel Advanced    | 46.9       | 95.2         |
| Others   | Perplexity           | 69.3       | 95.2         |
| Others   | Exa                  | 66.1       | 94.1         |
| Others   | Tavily               | 146.8      | 91.2         |
| Others   | Claude native search | 498.7      | 79.7         |
CPM: USD per 1,000 questions, end to end (answer-model tokens plus search and fetch calls at list price).
**Dataset**
TrialQA, also from LAB-Bench 2, asks for details teams look up in the ClinicalTrials.gov registry, such as a study's control arm, primary endpoint or planned enrollment. Two answer keys no longer matched the registry, so we updated them; two ambiguous questions were set aside, leaving 118.
**Evaluation methodology**
Every search API runs in the same agent loop with the same questions and the same grader, so the search layer is the only variable. Every arm answers with Claude Opus 5.5 (high effort). Claude native search is Claude Opus 5.5's built-in web search. Scores are the mean of three runs.
Cost is end-to-end per answer at list price: the answer model's tokens plus every search and fetch the agent makes, shown per 1,000 questions.
**Testing dates**
Evals were run in November 2026.
| Series   | Model                | Cost (CPM) | Accuracy (%) |
| -------- | -------------------- | ---------- | ------------ |
| Parallel | Parallel Fast        | 131.9      | 78.8         |
| Parallel | Parallel Advanced    | 107.9      | 79.3         |
| Others   | Perplexity           | 141.2      | 76.6         |
| Others   | Exa                  | 118.9      | 74.3         |
| Others   | Tavily               | 187.2      | 72.7         |
| Others   | Claude native search | 703.3      | 66.7         |
CPM: USD per 1,000 questions, end to end (answer-model tokens plus search and fetch calls at list price).
**Dataset**
MedBrowseComp asks multi-hop questions about FDA drug approvals that take several searches across regulatory, clinical and corporate sources. Company questions were re-keyed against FDA records to accept either reading of "latest approval", and patent and exclusivity questions with more than one valid answer were set aside, leaving 363 questions.
**Evaluation methodology**
Every search API runs in the same agent loop with the same questions and the same grader, so the search layer is the only variable. Every arm answers with Claude Opus 5.5 (high effort). Claude native search is Claude Opus 5.5's built-in web search; answers that reached the published answer file count as wrong. Scores are the mean of three runs.
Cost is end-to-end per answer at list price: the answer model's tokens plus every search and fetch the agent makes, shown per 1,000 questions.
**Testing dates**
Evals were run in November 2026.
Healthcare and life sciences teams often search for highly specific information. Developers evaluating search engines for these workloads may need to test whether they can find the latest drug label or pinpoint a result in a clinical trial table. To help developers measure how well search engines handle healthcare work, we built PWS-Health, a benchmark of 133 questions with verifiable answers. We adapted 83 from questions healthcare teams ask Parallel across 10 workflows and drew the other 50 from recent open-access clinical trials and meta-analyses. Parallel delivered 9.8 correct answers per dollar, 1.4× more than the next-best engine and 6× cheaper than built-in search.
Biomedical use cases depend on many specific details, such as an effect size reported in a results table. These kinds of details can be hard to find in an abstract or summary. LitQA3, part of FutureHouse’s LAB-Bench 2, tests whether search engines can find the right paper and pinpoint the answer across 168 questions about recent research. Parallel answered more of LitQA3’s biomedical research questions correctly than any other search engine tested, at the lowest cost per question.
When a trial changes its enrollment target or adds a study arm, healthcare agents need a reference they can trust. In existing workflows, ClinicalTrials.gov holds the latest trial updates, and a search engine needs to keep up with it. TrialQA, also from LAB-Bench 2, covers specific details teams look up in the ClinicalTrials.gov registry: a study’s control arm, its primary endpoint or how many patients it plans to enroll. Across the benchmark’s 118 questions, Parallel delivered top-tier accuracy at about a ninth of built-in search costs.
MedBrowseComp asks multi-hop questions about FDA drug approvals. Each question takes several searches to answer because what the engine finds in one source guides what it looks for next. For example, to identify which company holds the most recent approval for a drug, the engine first finds the approval in FDA records, then checks company filings to confirm the holder. The benchmark tests this kind of reasoning across regulatory, clinical and corporate sources. Parallel produced top-tier accuracy with up to 7.8× lower cost per correct answer compared to built-in search.
Vendor benchmarks tend to favor the vendor that builds them. To avoid that, we sourced the question mix from real healthcare demand, built each answer from official records, and ran every provider through the same harness, so only the search provider changes. The benchmark was built on the following pillars:
Here are five sample questions in the style of the set. They illustrate the question types; none are from the held-out set.
| Type | Question | Answer |
|---|---|---|
| Device regulatory | What 510(k) number and decision date did FDA give Boston Scientific's LUX-Dx II and LUX-Dx II+ insertable cardiac monitors in 2025, and what type of 510(k) was it? | K252593, decided Sep 12, 2025. Special 510(k), substantially equivalent; Class II, product code MXD. |
| Clinical trials | In Arcus Biosciences' Phase 3 trial of casdatifan plus cabozantinib in advanced clear cell renal cell carcinoma, what is the control arm, the primary endpoint and the planned enrollment? | Placebo plus cabozantinib; progression-free survival by blinded independent central review (RECIST 1.1); 720 patients (NCT07011719). |
| Drug labels | For which conditions is Novartis's remibrutinib (RHAPSIDO) indicated on its current US label, and when did FDA first approve it? | Chronic spontaneous urticaria and symptomatic dermographism in adults still symptomatic on H1 antihistamines. First approved Sep 30, 2025 (NDA 218436). |
| Pipelines | Regeneron is testing REGN7508 in a Phase 3 trial to prevent blood clots after total knee replacement. What does it compare against, and what is the primary endpoint? | Apixaban and enoxaparin. Primary endpoint: venous thromboembolism, including VTE-related death, through about day 12 (NCT07015905). |
| Published evidence | In the 2025 Nutrients trial of 8-hour time-restricted eating vs 25% calorie restriction in adults with type 2 diabetes, how much weight did each group lose vs controls by month 6? | Time-restricted eating: −3.38% (p = 0.008). Calorie restriction: −1.80% (p = 0.32, not significant). |
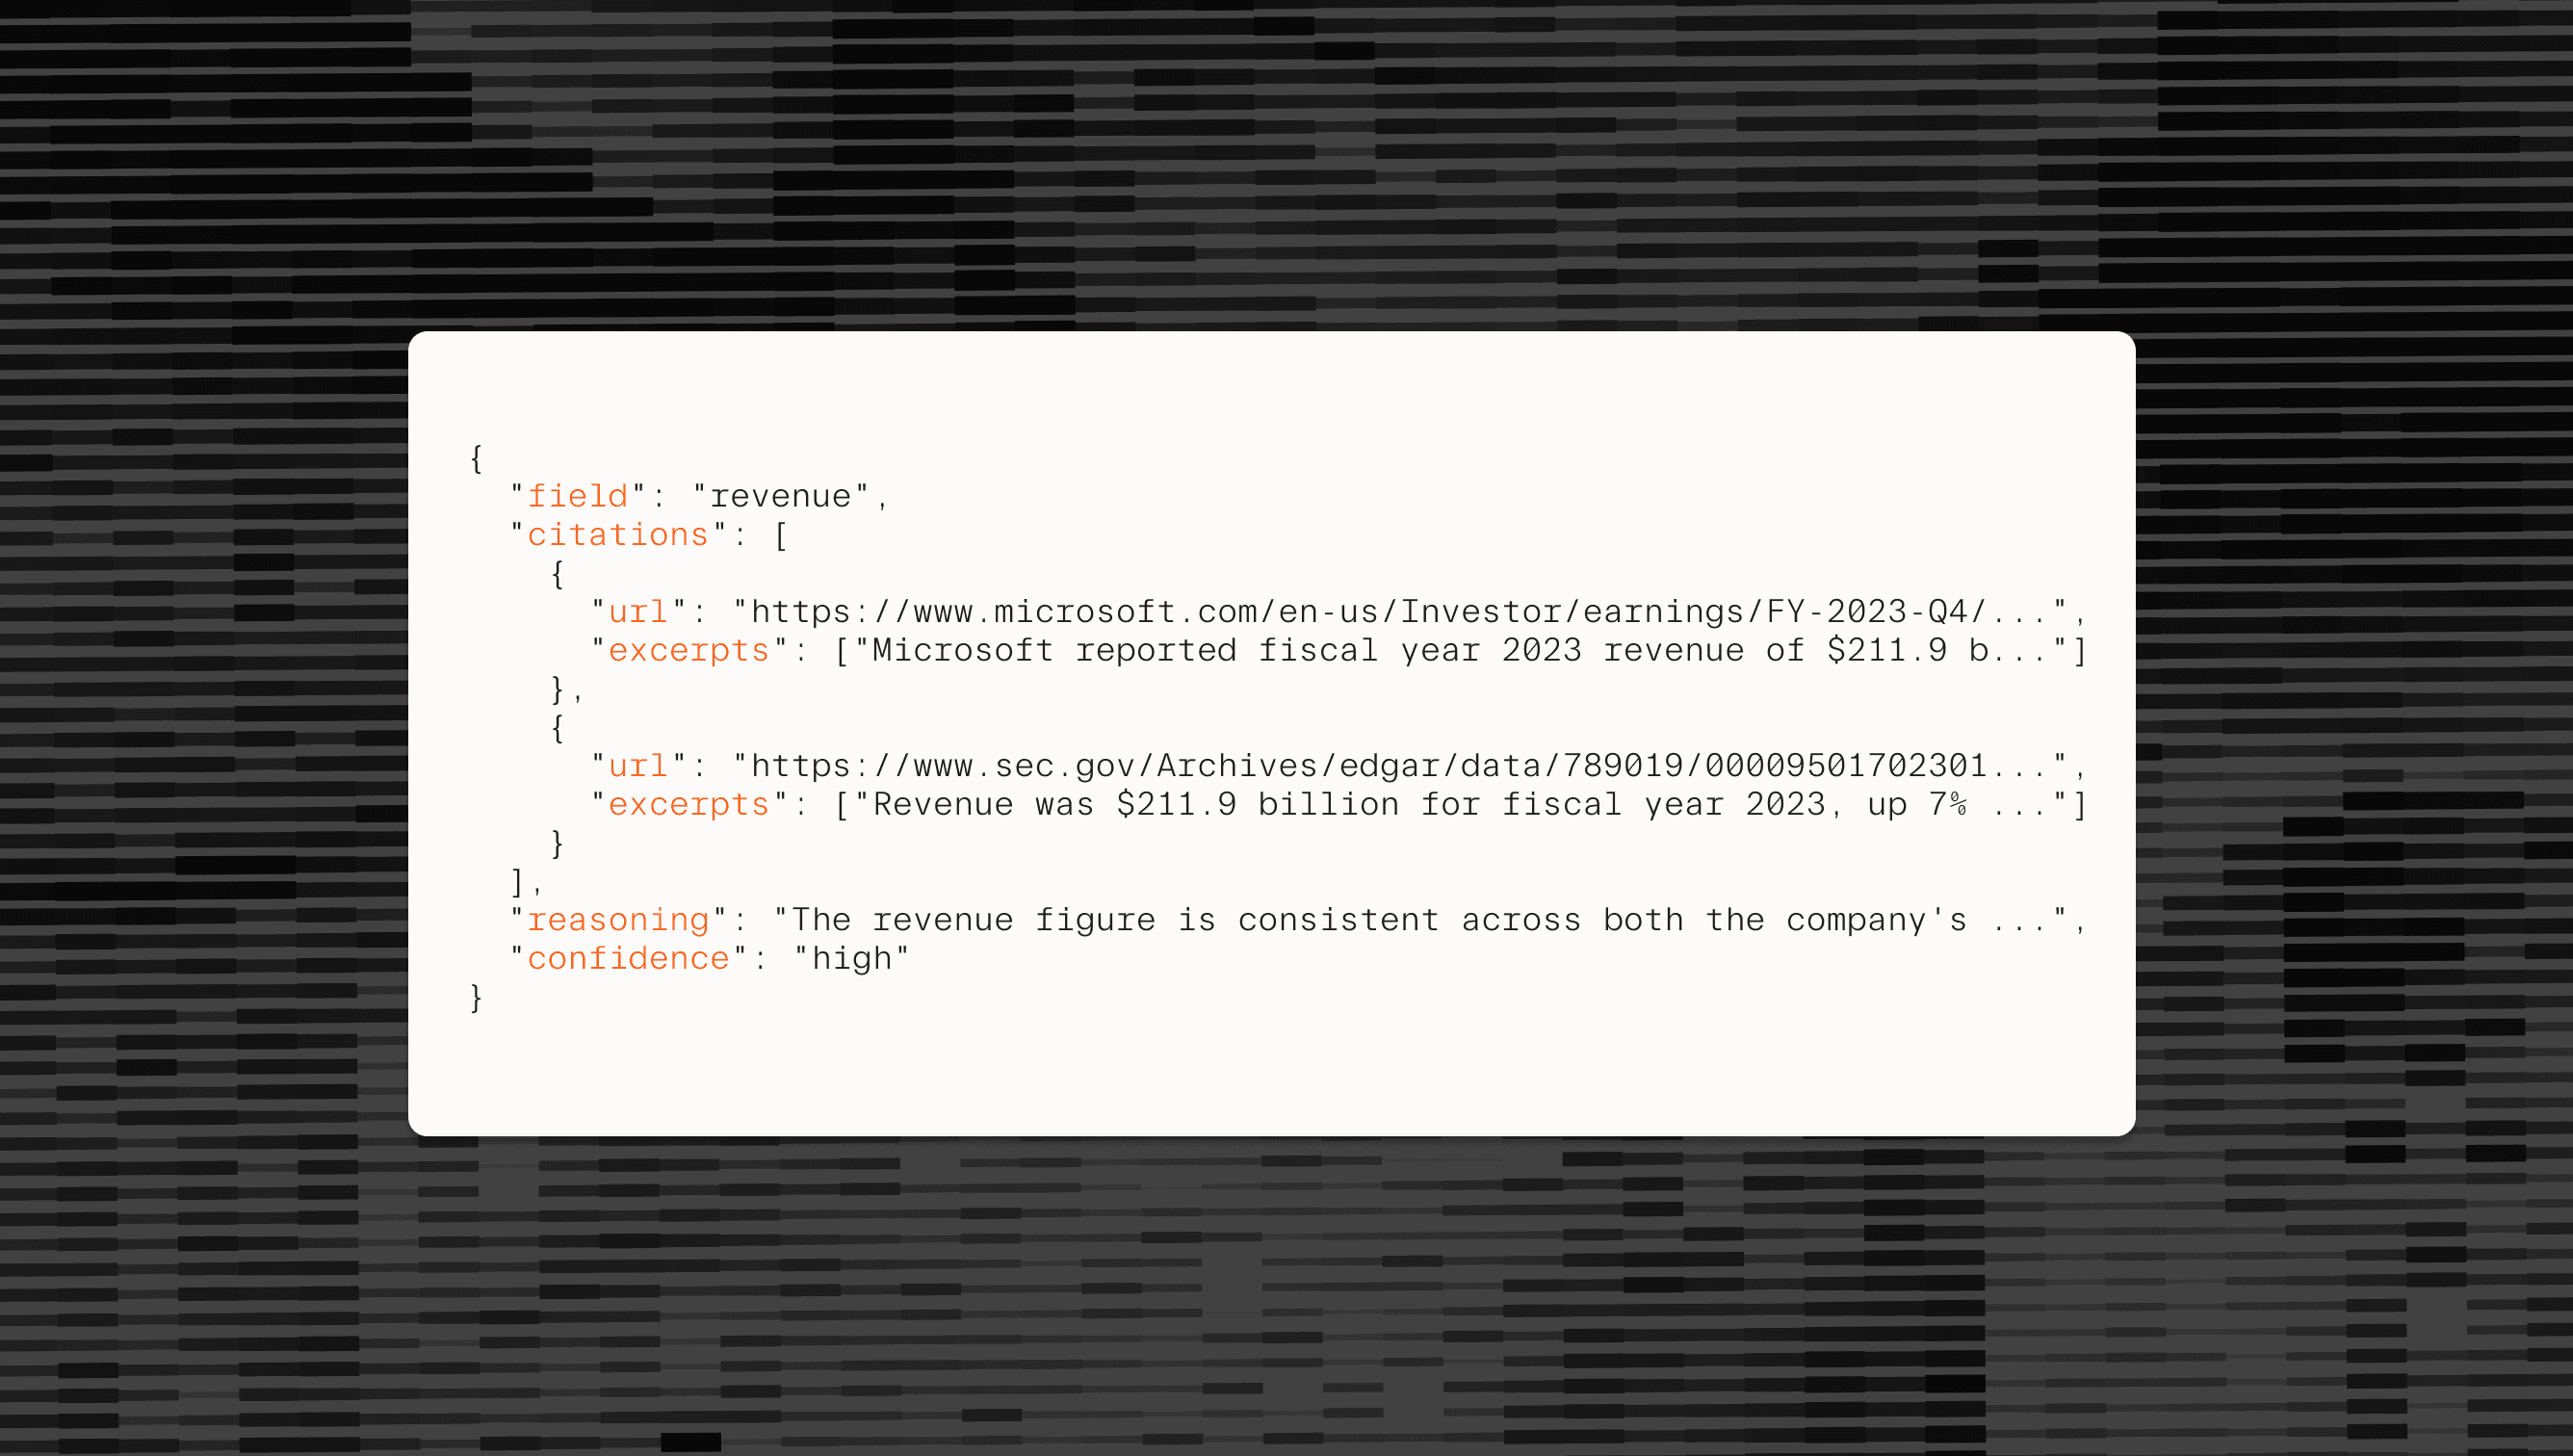
Accuracy is critical in healthcare because an outdated drug label can mislead a clinician making a treatment decision. To trust a healthcare agent’s answer, clinicians and researchers need to see the specific label, guideline or trial result that supports it. Citations from a search provider give these teams a record they can use to investigate errors and verify claims during clinical and compliance reviews. Parallel ranked first for accuracy on all four healthcare search benchmarks, with its largest lead on LitQA3, where it scored 5.7 percentage points ahead of Exa.
Healthcare answers often sit deep in a paper, in a methods section or a safety table. They’re rarely in the abstract. To show the difference search makes, we ran questions from LitQA3 (LAB-Bench 2) through the same agent and answer model, Claude Opus 5.5. Only the search engine changed.
Healthcare teams use Parallel to track drug and device approvals, monitor clinical trials, and keep provider and facility records up to date.
More than 500 medtech companies use AcuityMD to see where procedures take place and which surgeons perform them. To keep that data current, AcuityMD’s data team runs Parallel’s Search, Extract, and Task APIs in batches. The team checks whether clinics are still open, identifies which health systems their offices belong to, and looks up where physicians completed their fellowships.
In five months, AcuityMD verified 574,000 records at about one-fifth the cost of using a frontier model alone. Every link Parallel returned was live. Read the AcuityMD case study[Read the AcuityMD case study].
“Accuracy and cost at scale were non-negotiable for us. Parallel confirms every URL it returns is live, its cost holds up across hundreds of thousands of records, and it gives us more breadth and recall than a frontier model on its own. That’s why every new data project on our team starts with Parallel.”
> “Accuracy and cost at scale were non-negotiable for us. Parallel confirms every URL it returns is live, its cost holds up across hundreds of thousands of records, and it gives us more breadth and recall than a frontier model on its own. That’s why every new data project on our team starts with Parallel.” > > — Greg Davis, Senior Data Program Manager, AcuityMD
With Parallel, an agent can track how far a drug candidate has progressed, add relevant publications to a provider’s profile, or check whether a provider has run a clinical trial. Pick the workflow that matches your agent's problem, and every response will come with a cited source.
We built an open-source cookbook recipe so you can turn a CSV of drugs into cited asset profiles with Parallel’s APIs. It runs the Task API with Source Policy limited to regulator sites like FDA and EMA, plus free ClinicalTrials.gov and PubMed Data Connectors. Then it checks every trial and paper ID against its public registry. The output is a PDF profile per drug, with a research basis page listing every source.
It’s a lightweight starting point based on workflows we’ve seen work well in production. Clone it from our open-source repo[our open-source repo] and adapt it to your own drugs.
Start building for free[Start building for free] or dive into our docs[docs].
Contact us[Contact us] to learn more about enterprise plans with SOC 2 Type 2, zero data retention, a BAA for HIPAA, EU data residency, SSO, and specialized indexes for healthcare domains.